Read More


Recognized for AI Excellence at 2026 Globee® Awards - Read More

Nihar Raval
Most "remote team problems" aren't really about remote work. A distributed team with clear ownership, honest requirements, and a working review process ships fine. A distributed team without those things falls apart in a way that's easy to blame on time zones instead of on the gaps that were always there. Proximity was just covering those gaps before.
Fixing it isn't a problem. It's getting clarity on a handful of decisions like who owns delivery, how the team talks to itself, what "done" means. That's the structure Radixweb establishes these foundations before the first sprint starts, aligning dedicated teams around a shared product roadmap. The rest of this guide explores how that works in practice.
Distributed teams don't fail because of distance. They typically fail when ownership, requirements, and review discipline stay implicit instead of designed. Strong remote execution depends on clear communication frameworks, structured delivery practices, and deliberate management choices that prevent teams from quietly unraveling behind a green sprint dashboard.
| Aspect | Details |
|---|---|
| What does this guide covers? | Async communication and SLAs, cross-time-zone agile workflows, remote onboarding, code reviews and CI/CD, clear acceptance criteria, productivity measurement, and the tools and security practices that enable distributed teams. |
| Who should read this? | Engineering managers and VPs of Delivery running distributed teams; CTOs and founders deciding between in-house, staff augmentation, or a dedicated remote team; delivery and program managers overseeing offshore engagements; product leaders working day-to-day with distributed engineering teams. |
Strip away the jargon and a remote software development team are just engineers, QA, design, and delivery leadership working from different places instead of one office. Managing it well still comes down to the same fundamentals as managing any engineering team. Effective remote team management requires clear requirements, sprint accountability, real code review, and honest communication. Nothing about being remote changes anything in that list.
What changes is how much of that must be spelled out on purpose. In an office, half of it happens by accident. Someone overhears an architecture debate, catches a UI inconsistency walking past a monitor, or gets a two-minute answer instead of waiting a day for one. None of that exists on a distributed team unless someone builds a replacement for it deliberately.
It’s also worth untangling the vocabulary, because ‘remote’ gets used loosely. A team can be remote-but-same-country, nearshore in a neighboring time zone, offshore on the other side of the planet, or some hybrid of client staff and an external team. The distinction matters because it determines how much natural overlap exists for synchronous work, what legal and contractual structures apply, and who carries day-to-day management responsibility. None of those distinctions change the underlying engineering discipline required; they change how deliberately that discipline has to be designed.
Before communication protocols or sprint ceremonies matter, someone has to decide who owns delivery. That decision shapes everything downstream. Also, it's the one most companies skip past on their way to picking a project management tool.
| Model | Best For | Main Advantage | Main Risk |
|---|---|---|---|
| Build in-house | Large organizations with ongoing, long-term product needs | Full control and IP ownership | High recruiting cost; specialist scarcity |
| Staff augmentation | Closing a specific skill gap inside an existing team | Fast access to specialist skills | Client retains full delivery ownership |
| Dedicated remote team | Building or scaling a product without an internal engineering org | Continuity, shared product context, vendor delivery support | Requires clear governance from day one |
| Full-cycle outsourcing | Companies that want end-to-end ownership handed to a partner | Single accountable delivery owner | Requires trust in the partner's process |
In-house still wins for organizations with sustained, multi-year engineering needs and the budget to fight for scarce specialist talent. However, outsourcing pre-vetted remote engineers for a specific stack pays off well in certain scenarios. Say if a company is shipping its first serious product, entering a new market, or trying to move faster than internal capacity allows. A six-month local hiring cycle for a handful of open roles here just isn't competitive with how fast the market moves.
The signals that point toward remote are pretty consistent:
Highly sensitive, hardware-linked, or still-fluid discovery work is usually better suited to close, in-person collaboration, at least in the earliest phases.
What remote collaboration typically doesn’t guarantee:
A remote team run without a deliberate process cost more in rework than it saves at an hourly rate. The real expense lies in repeated fixes, wasted effort, and missed deadlines that quickly outweigh any savings from lower hourly costs.
Leave the communication structured undefined, and a team will invent its own organic rules anyway. Organic patterns in communication, updates, and handling urgency for distributed teams usually suit whoever's sending the message, not whoever has to respond to it. Here are four decisions that need to be nailed down before sprint one.
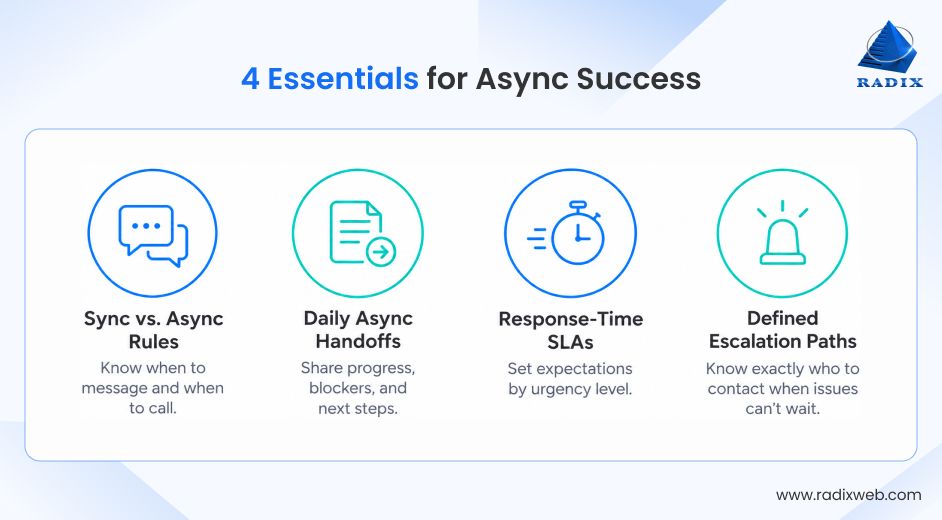
A workable rule of thumb helps teams avoid confusion. Put this in writing, so defaults don’t drift to whatever is easiest for the sender.
A simple end‑of‑day note replaces the overheard context of co-located teams and closes time zone gaps without adding meetings. This habit is one of the more practical ways to close time zone gaps in outsourcing.
Clear tiers prevent frustration and set expectations for when responses are due. By defining response windows up front, teams avoid misaligned expectations, wasted follow‑ups, and the silent delays that erode trust across time zones.
When async cycles aren’t enough, engineers need clarity on who to contact. Production incidents especially require skipping the queue.
None of this needs a formal policy nobody reads. One page covering the sync/async rule, the SLA table, the handoff format, and who to escalate to is usually plenty. Teams that skip it tend to build it anyway a few sprints later, right after the first missed handoff makes the cost obvious.
Remote teams succeed when they replace co‑located shortcuts with explicit frameworks. This section explores the practices that keep distributed teams aligned across sprint ceremonies, enforce quality through disciplined code review and CI/CD pipelines, remove ambiguity with well‑defined requirements, and measure developer output with metrics that reflect real value instead of superficial activity.
Sprint ceremonies force decisions on a distributed team that a co-located team never even has to think about. This is because a shared room makes those decisions automatically. These requirements are absolutely critical for maintaining agility in distributed teams.
This is the one ceremony that doesn't really survive going async. Ambiguity in acceptance criteria needs to get resolved in real time. A clarifying question that takes 24 hours to answer over chat either blocks an engineer or gets them guessing. Teams still often start with best practices in setting up an agile distributed team, since planning usually needs the most redesign for distance. Put planning inside whatever overlap window exists.
A synchronous standup that forces one team to log in at 7am or 10pm reliably produces resentful attendance and thin updates. A written async standup gives engineers time to think about what they write instead of what they say in thirty seconds. This removes the time-zone inconvenience entirely.
Send a short, recorded walkthrough before the live sprint review. Stakeholders watch it on their own time, and the live session becomes a conversation about decisions instead of a first reaction to something they're seeing for the first time. This is exactly the moment a fundamental direction question tends to surface, after the work is already done.
This involves collecting anonymous inputs before the live retrospective through tools like EasyRetro or Retrium. It generally produces more honest feedback from remote engineers than asking them to raise problems live on a call with the client present. Understanding how a standard scrum sprint actually runs is required to tighten the rhythm before adopting the format any further.
When adapted for distributed teams, Agile practices maintain clarity, alignment, and delivery momentum across time zones.
A new hire on a co-located team picks up context by overhearing architecture debates and noticing what senior engineers prioritize. They absorb the unwritten hierarchy just by being in the room. A remote hire misses all of that unless someone documents it clearly from the start.
This can be a first-week breakdown after a specialist joins the team:
| When | Focus | Expected Outcome |
|---|---|---|
| Day one | Environment setup only | Verified working local build by end of day |
| Days two and three | Codebase walkthrough with a senior engineer | Understanding of data model, API structure, and conventions |
| Days four and five | First small, bounded task | A reviewable pull request that tests convention understanding |
There’s a difference between dropping a specialist into an existing team and strategically onboarding external developers into existing teams. Give the new engineer one named buddy for the first 30 days; one specific senior person who's on the hook for their ramp-up. This structure actually makes them productive by week two instead of week six.
On a co-located team, review happens formally in the PR and informally in the hallway. On a remote team, the PR is the only mechanism. This means without real discipline, it turns into a rubber stamp somebody clicks through under deadline pressure. Remote teams maintain code quality through structured review processes and automated delivery controls. These are the practices that make those quality gates effective:
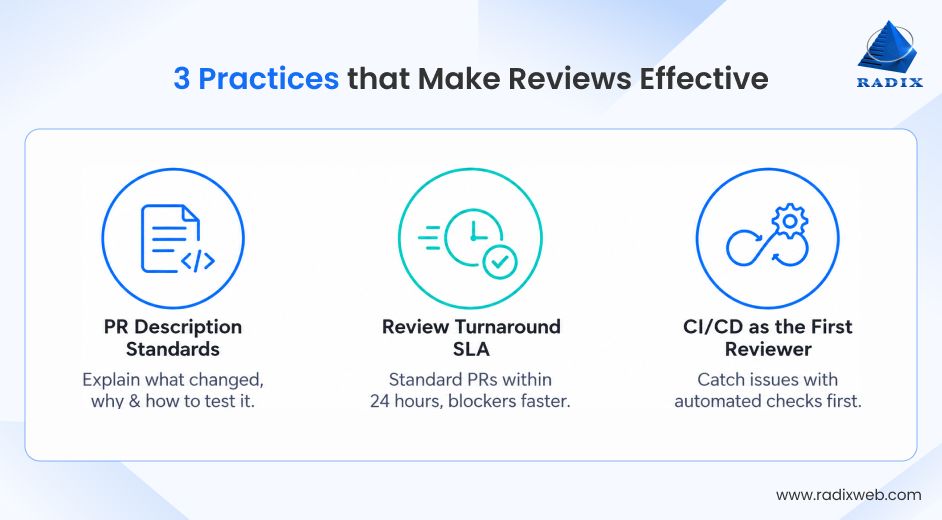
Every pull request should state what changed, why, what the reviewer should focus on, and how to test it locally. "Fixed the bug" isn't a description, it's notification. It forces the reviewer to reverse-engineer the intent before they can even start.
A standard review earns a 24-hour turnaround. Anything blocking another engineer's work gets four, during business hours. Without a defined SLA, review time expands to fill whatever space sprint pressure leaves it. Velocity numbers stop meaning much once stories are sitting "in review" for days at a time.
Unit tests, integration tests, linting, static analysis, all of it runs before any human sees the code. A PR that fails automated checks bounces back to the author before it wastes anyone's review time. On a distributed team especially, the "tests are failing, fix it" back-and-forth can otherwise eat an entire async cycle for no good reason.
The single most consistent quality failure on remote teams is the review stage compressed into the last two days of a sprint. Teams that rely on software development outsourcing with end-to-end ownership, own delivery across the entire software lifecycle, tend to catch this earlier. This is because someone is accountable for the defects that surfaces in the next sprint, not just the points closed in this one.
Bad requirements hurt a remote team more than a co-located one, simply because there's no hallway conversation left to catch the gap between what got written and what was meant.
Vague criteria read something like ‘Users can log in with their email address.’ A well-defined criteria, however, is ‘a user entering the correct email and password reaches the dashboard within two seconds while the incorrect password shows a generic error that doesn't reveal which field was wrong. Five failed attempts to lock the account for 15 minutes with a visible countdown.
Writing requirements this way takes longer for sure. But it also removes days of mid-sprint back-and-forth that would otherwise happen once an engineer is already halfway through building out the wrong thing. Authentication, payments, and any project touching personal data shouldn't ship without specific requirements being properly laid out.
A story with user interface changes should never enter a sprint without an approved wireframe, because wireframes act as the contract between product and engineering. They clarify intent, prevent misinterpretation, and give developers a concrete reference point, reducing wasted cycles on assumptions that later get overturned. For distributed teams especially, missing wireframes stall progress for days since quick clarifications aren’t possible. Treat them as a prerequisite for sprint planning, not a nice‑to‑have, because they anchor design decisions, reduce churn, and keep delivery timelines honest.
Validate a feature against its acceptance criteria before marking it complete, not after. That discipline is exactly what makes building software around specific delivery requirements possible instead of shipping something generic and hoping it's close enough. A short, recorded walkthrough lets a product owner or QA catch a gap before the story closes, which is a much cheaper place to catch it than the end-of-sprint demo, and it saves the awkward live moment where a stakeholder spots the problem in front of everyone else.
Remote developer performance management defaults to the wrong metrics when managers don't have visibility into the work.
Metrics That Feel Safe but Predict Nothing
Metrics That Actually Predict Quality
A remote engineer's performance conversation has to be more explicit and structured than a co-located one. The ambient signals a manager normally relies on, like seeing someone at their desk, in the room, interacting with the team, just aren't there.
Estimation accuracy gets misread more than any other metric on this list. Consistent underestimation usually points to hidden dependencies or a real skill gap. Consistent overestimation is rather a padding to guarantee an easy sprint.
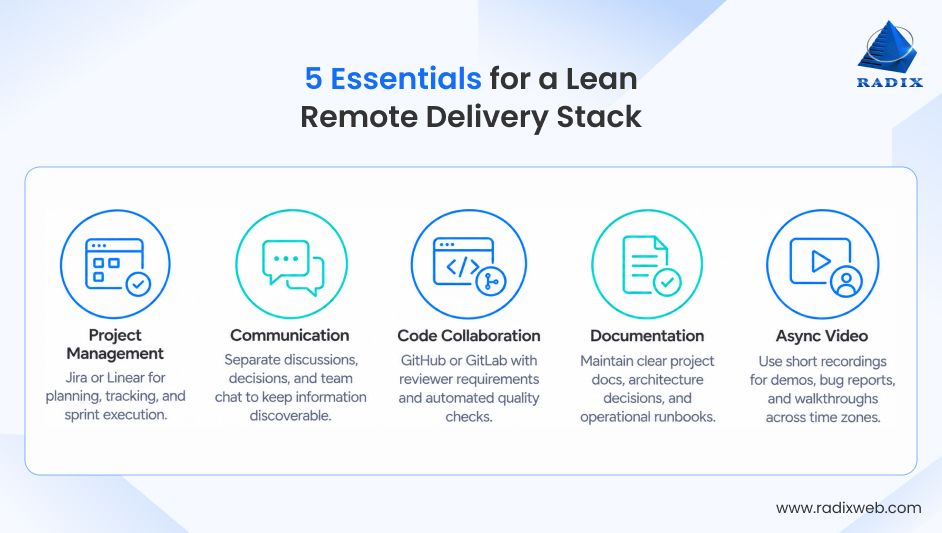
Distributed engineering in 2026 demands more than just good intentions. It requires deliberate choices about the tool stack, disciplined adoption of AI coding practices, realistic time zone models, and proactive security compliance. Together, these foundations determine whether remote delivery scales smoothly or collapses under sprawl, inconsistency, and risk.
Tool choice is a communication architecture decision, not a preference. Each tool reinforces a default behavior: a chat app reinforces rapid response, email reinforces delayed response, async video reinforces thinking before speaking. Choose the stack to reinforce the norms the team has agreed to, not to collect the maximum number of integrations.
AI coding tools are mainstream in 2026, but their benefits only hold if teams apply consistent discipline.
Underneath any AI-assisted workflow sits a more basic requirement that teams sometimes skip past. Understanding what clean data means for AI project matters just as much for internal tooling or evaluating AI‑generated output as it does when developing a dedicated machine learning build.
The overlap window between a client and a remote team decides which ceremonies can be synchronous, and which must be async out of necessity. Get it wrong and there are really only two ways it goes. A team that forces synchronicity across a ten-hour gap and burns out the smaller side. Or a team that treats everything async and loses the real-time collaboration that some decisions genuinely need.
| Geography Pairing | Typical Overlap | Practical Model |
|---|---|---|
| US East Coast + India | A narrow window near the start of the US day and the end of the India day | One synchronous ceremony per day, at most |
| US West Coast + India | Little to no natural overlap under standard hours | Primarily async, with scheduled sessions where one side shifts hours |
| UK / Western Europe + India | Several hours of genuine overlap | Most workable geography; planning, review, and architecture discussions can run synchronously |
Synchronous hours are scarce no matter the geography. They should be spent on issues that needs real-time collaboration like sprint planning, architecture discussions, sprint review, escalation. Synchronous hours shouldn’t accommodate standups, code review, and status updates.
Security for remote teams usually gets built too late. They should be configured before the first engineer gets access to anything sensitive, instead of after the first concern getting raised.
GDPR applies to the processing of personal data of EU residents, regardless of where the engineering team is physically located. The processor agreement between client and vendor must explicitly define processing purposes, data categories, and security requirements in writing. This is exactly the kind of allocation that are addressed in the basics of outsourcing software development models. Additional requirements around cross-border data transfers, data residency, or sector-specific compliance obligations may also need to be incorporated depending on the jurisdictions, regulations, and data types involved.
The two-tier problem occurs when a distributed team develops two classes of employees; ones who are close to decision-making and those who are only involved in execution. It is probably the single most reliable predictor of remote engineer attrition, and it's the thing most distributed teams underinvest in. It shows up when remote engineers start feeling like ticket processors instead of people actually building the product.
Integrate remote developers from day one, and don’t keep them isolated. Companies that hire and onboard remote developers with inclusion in mind bake these habits into the engagement early, avoiding attrition later.
Most remote team problems are obvious in hindsight and completely manageable in advance. The signals that precede a real velocity collapse usually show up three to six weeks before things get bad. Each of these has an individually reasonable-sounding explanation, which is exactly why they get ignored.
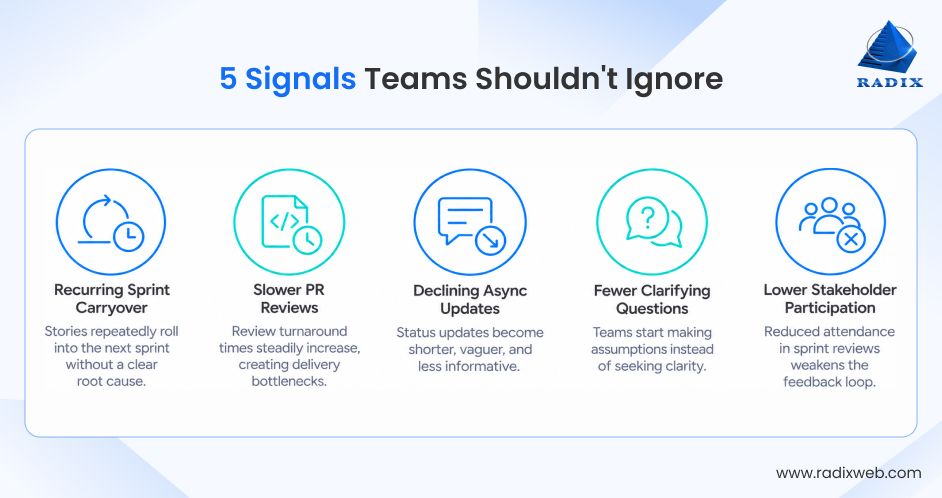
Each of these maps to a specific fix like revisit requirements, add review capacity, clarify ownership, get the stakeholder back in the room. Carrying a signal into the next retrospective and hoping it resolves itself is usually how a manageable problem turns into a visible one.
Use the following decision matrix to evaluate remote or offshore development partners on criteria that directly impact delivery quality, risk, and long-term collaboration.
| Key Questions to Ask | What “good” looks like | Red flags to watch for |
|---|---|---|
| Can you show relevant project experience in my specific category, not just a broad portfolio? | Named case studies in similar industry, architecture, and scale; outcomes like defect reduction, faster releases, or compliance achievements. | Only generic “web/mobile/app” examples; no projects comparable to your product, market, or complexity. |
| How do you handle compliance, security architecture, and data handling for remote/offshore engagements? | They raise security and compliance in the first conversation; clear policies on access control, secrets management, VPN/MDM, and PII handling. | Security is “configured later”; vague answers; compliance only mentioned after you ask. |
| Who is accountable for delivery, and how do you document staffing changes and technical decisions? | One named delivery owner; written architecture decision records; documented staffing changes; clear escalation paths. | “The team” owns everything, but no single accountable person; decisions live only in chat or calls. |
| What does your onboarding, code review, and quality gate process look like in practice? | Concrete onboarding plan (env setup, ADRs, buddy, first week tasks); defined PR standards, review SLAs, CI/CD checks, release criteria. | Slides full of “best practices” but no actual checklists, templates, or pipeline configuration. |
| Which engagement model do you recommend: staff augmentation, dedicated team, or full outsourcing and who owns delivery in each? | Clear explanation of models: augmentation (you own direction), dedicated cross‑functional team (shared ownership), full outsourcing (vendor owns delivery end‑to‑end). Recommendation tied to your maturity and goals. | They push one model by default (usually cheapest) without explaining ownership, responsibilities, or trade‑offs. |
A partner that treats compliance and quality gates as a downstream concern will cost more in remediation than the hourly-rate difference ever saves. Companies assembling cross-functional expertise often evaluate the business value of hiring dedicated specialists focused on one project against staff augmentation and full outsourcing. Side-by-side, each of these allocate delivery ownership a little differently.
Discipline Is the Cue for Successful Remote Teams in 2026
None of the failure patterns in this guide are actually about distance. They’re about the parts of running a team that a shared office used to paper over. Leaders who want to fix those gaps generally invest in hiring a dedicated remote development team when introducing disciplined practices into an existing engineering setup. Distributed teams that consistently produce strong output aren't staffed with the most talented individual engineers. They're the ones with deliberate communication design, requirements that don't leave room for guessing, consistent sprint discipline, and management that treats a remote engineer as part of the team building the product rather than a vendor processing tickets for it. leave room for guessing, consistent sprint discipline, and management that treats a remote engineer as part of the team building the product rather than a vendor processing tickets for it.If you're figuring out how to structure or fix a distributed engineering effort, outsource work to the right remote teambefore the next sprint gets planned. We'll walk through what a properly built remote engagement looks like for your project specifically.
Ready to brush up on something new? We've got more to read right this way.